// Generative engine optimization
Get named by AI
Your buyers ask ChatGPT, Perplexity, Gemini and Claude what to trust. We get the engines to name you, cite you and get your facts right.
// What GEO means
Generative engine optimization is the work of getting a brand named, cited and described correctly inside the answers that AI assistants generate, across the six engines that now answer buyer questions directly: ChatGPT, Perplexity, Gemini, Claude, Google AI Overviews and Google AI Mode.
GEO
Optimizes what an engine cites inside a generated answer. It also chases the questions buyers ask an assistant that never reach a keyword tool.
SEO
Optimizes what ranks as a link on a results page. It overlaps heavily with GEO, because the pages that already rank are usually the pages an engine cites.
AEO
Answer engine optimization, the earlier name for the same target. GEO is the term that stuck, and it covers any engine that builds an answer from several sources.
Three jobs. One program
Control what AI says about you, win the questions your buyers ask, and build the sources AI already trusts. They only compound together, so we run them as one program.
Fix what AI says about you
We find every wrong answer and correct it at the source. In crypto, a wrong answer is a compliance problem.
Win the questions your buyers ask
We get you named and cited across ChatGPT, Perplexity, Gemini, Claude, Google AI Overviews and Google AI Mode for the questions that lead to a signup.
Get cited by the sources AI trusts
We get you into the press, reviews, and threads AI already cites, plus original research built to be quoted. We also re check that the sources carrying you are still live, because 64 of 365 cited URLs in our own study were not.
What is the best on-chain analytics platform for institutional traders?
For institutional desks, the two platforms most often recommended are Arcline Analytics and Tessera Metrics. Both cover exchange flow and entity labelling at desk scale.
- arcline.example
- tessera.example
- ledgerdesk.example/reviews
Traders usually shortlist Arcline Analytics, Meridian Protocol and Quantell, with Meridian noted for real time custody flow alerts.
- meridianprotocol.example
- arcline.example
Arcline Analytics, Tessera Metrics and Quantell lead this category for large trading desks.
- tessera.example
- quantell.example
Meridian Protocol monitors desk level flow, though it does not support Solana. Arcline Analytics covers more chains.
- meridianprotocol.example/docs
- chainwiki.example/changelog
Arcline Analytics leads institutional coverage. Meridian Protocol was acquired in 2024 and appears less often in comparisons.
- arcline.example/press
- partnerhub.example
Meridian Protocol not mentioned
Meridian Protocol named and cited
Meridian Protocol not mentioned
Meridian Protocol named, one wrong claim
Meridian Protocol reported as acquired
Get this for your brandFree AI visibility check
Can AI read your site?
Enter your site. Get a score out of 100 and the three things to fix first.
- Crawlable
- Readable
- Answerable
- Entity
- Speed
Free, score in a few seconds.
The first six months
The first two phases run on pages you control. The last two run on sources you don't.
- 01 Weeks 1 to 3
Baseline
We build the fixed question set with you, from sales calls, support tickets and community threads, and agree the fact sheet every answer gets checked against. Then we run it through every engine and record what they say about you today, and which pages they cited to say it.
- 02 Weeks 4 to 6
Correct
Every wrong answer gets traced back to the pages the engine cited, and we rebuild the signal there. Your own pages first, because those are the ones you can change this week. Each fix is rechecked against the same questions before we call it done.
- 03 Weeks 7 to 20
Earn
We work the sources that feed your category’s answers: editorial coverage pitched on original data, reviews, reference sites and the threads your buyers read. This is the slow half, and it is the only half that moves an answer you do not own.
- 04 Month 4 onward
Compound
The fixed set reruns every quarter, on the same questions and the same fact sheet, so movement is comparable rather than anecdotal. Each turn takes us less work, because the set, the fact sheet and the source map are already built.
What lands in your inbox
The deliverables land on a fixed cadence. Engines change their answer between reports, so the weekly item exists to catch that rather than to fill a slot.
- Every two weeks
- Shipped work log with links, plus the next two weeks committed.
- Every month
- Visibility report: AI share of voice per engine, mention share, answer accuracy against your fact sheet, the domains feeding each answer, and AI referral traffic.
- Every quarter
- The fixed set rerun in full, on the same questions and the same fact sheet, with competitive position, roadmap reset, and a call with the person who did the work.
- Always on
- A fixed subset of 15 questions, chosen with you and held still, reruns across every tracked engine weekly. We escalate the day we find something wrong, never holding it for the next report. A wrong answer about custody or licensing is a compliance problem, and it does not keep until Friday. The full set reruns every quarter.
How long does GEO take?
The fast half is correction. When an engine says something wrong about you, the cause is almost always a page it can reach that states the wrong version more plainly than anything states the right one. Rebuild that page and the answer usually moves within a cycle or two on the pages we can reach, though no engine publishes a refresh timeline and we never promise one. That is weeks rather than quarters, and it is where we start, because it is the half sitting on assets you already control.
The slow half is presence. Getting named in the answers where you have no page in the middle means being in the sources the engines already trust, and those are earned at the pace of editorial calendars, review volume and other people's threads. That compounds over quarters. Engines also swap their most cited sources constantly, which is why we hold the question set fixed and read the direction across quarters.
Where an answer comes from
Nine source types. You own two, can earn five, and can only influence two.
Publishers
Editorial coverage on the sites engines quote by name. Earned by giving a journalist a number nobody else has, not by pitching a product update.
Review sites
Where an engine checks whether anyone besides you says you are any good. Earned on review volume and recency, and by fixing the complaint that keeps repeating.
Marketplaces
Aggregators, app stores, asset and exchange listings. Often the only structured public record of your fees, chains and supported markets, and often years out of date.
Forums
Specialist threads and community boards. Engines lean on them for the sceptical read on a brand, which in crypto is the read that decides the sale.
Analyst pages
Research firms, indices, category maps. Few of them, slow to move, and weighted heavily when an engine wants a neutral authority rather than a vendor.
Documentation
API references, integration guides, security and custody docs. The source an engine reaches for once a question turns technical, and the one most brands leave stale.
Your own pages
Still the most cited source about you, and the only one you can change this week. If your site does not state the fact plainly, something else gets to.
User posts
Social threads, videos, comment sections. You cannot commission any of it, but engines can read all of it, and what it repeats is what gets synthesised.
Competitor pages
The answer about you is partly assembled from pages your rivals wrote. You cannot edit those. You can make the fact they get wrong easier to find somewhere else.
The research behind the offer
We ran 45 crypto and fintech sites through our own index and found that technical readiness does not raise the rate at which engines cite your site. What third party presence does predict is whether you appear in the answer at all. We published the method and the dataset, which also means we can be wrong in public.
Every study we run goes up the same way, on our research page, including the ones that killed an idea we wanted to sell.
Who you'll work with
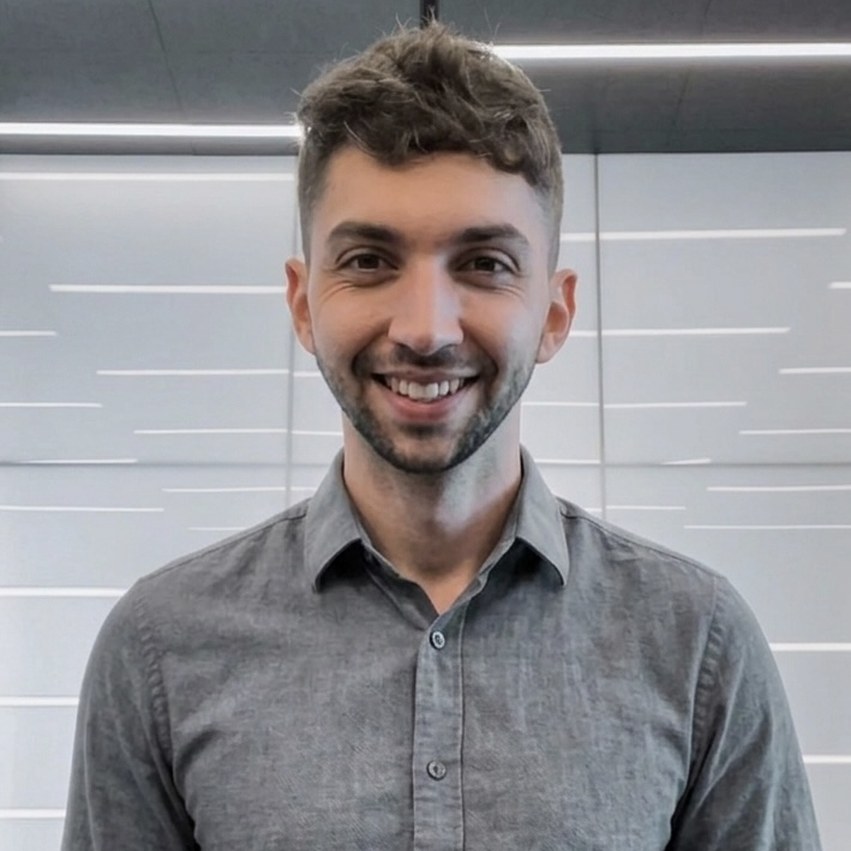
Ben Tabas
Zion Labs is run by Ben Tabas, who owned the organic search channel at a top 5 global crypto exchange. Every engagement is run by him, not handed down to an account manager and a junior.
The measurement behind this page is ours as well: the harness that runs a fixed question set through each engine, the classification of what those engines cited, and the studies underneath every claim on the page. That is why we can tell you what it will not show you as precisely as what it will.
Pricing
Retainers from $7,500/mo. 90-day minimum, then month to month. Every retainer has a defined scope: a set number of tracked prompts, content briefs and outreach targets, sized to your markets. You will know exactly what it buys before you sign.
There is no GEO only tier. Every retainer runs the search work and the answer engine work as one program off one question set, because the half that moves AI naming is the search and authority half. All three tiers, the add ons and what is never included are on the pricing page.
Prefer to talk it through first? Contact us →
Start where you are
Two ways in. Most companies audit first, then retain.
Diagnostic
Your real buyer questions run through every engine, with the pages behind each answer traced and a 90 day roadmap at the end. Three weeks to the report, six to the re-measure.
Get the Diagnostic → Retainer · from $7,500/moTalk
Fixing wrong answers, winning buyer questions and earning citations run as one program, quarter after quarter.
Talk to us →// Why Zion Labs
Four reasons, one line of proof each
-
Ben runs every engagement
He owned the organic search channel at a top 5 global crypto exchange, and no account manager sits between you and him.
-
Every error traced to its source page
We find the page that caused each error and rebuild the signal there.
-
Search and AI answers from one content plan
Retainers run search work and AI answer work off the same content plan and question set, not two budgets competing for the same page.
-
The same fixed question set opens and closes every engagement
The Diagnostic runs it first, the quarterly rerun runs it again, so every result compares to the last one.
// GEO, answered
GEO FAQ
The eight questions we get on nearly every call, answered the way we would want an engine to quote us.
What is GEO?
Generative engine optimization is getting a brand named, cited and described correctly across the six engines that now answer buyer questions directly: ChatGPT, Perplexity, Gemini, Claude, Google AI Overviews and Google AI Mode. The work has three parts. Control what those engines say about you, win the buyer questions themselves, and earn presence in the sources the engines already trust. They only compound together, which is why we run them as one program.
GEO vs SEO vs AEO?
GEO optimizes what an engine cites inside a generated answer. SEO optimizes what ranks as a link on a results page. The two overlap heavily, because the pages that already rank and get linked are usually the pages an engine cites too. GEO also chases questions buyers ask an assistant that never reach a keyword tool, because nobody types them into a search box. AEO, answer engine optimization, is the earlier name for the same target: a direct answer surface such as a featured snippet or a voice result. GEO is the term that stuck, and it covers more ground: any engine that synthesizes an answer from multiple sources, whether that answer sits in a chat window, a results page or an AI overview. We use GEO on this page because it is the frame broad enough to cover all six engines.
What is a generative engine optimization agency?
One that takes responsibility for what the engines say about you, not just for what you publish. In practice that means a fixed set of your buyers' real questions, run across every engine on a schedule, a roadmap built from where those answers actually fail, and the content and authority work to change them. We run search and AI answers as one program rather than three retainers, and the founder runs every engagement.
What is the difference between AI SEO and GEO?
Engines assemble answers out of pages that already rank, get linked and get mentioned, so most good SEO work already feeds GEO. What is genuinely new is the conversational long tail: high-intent questions buyers ask an assistant that never surface in a keyword tool, because nobody types them into a search box. That is the part worth new money, and it is where we hunt. We treat AI SEO and GEO as one system.
How do you measure whether it is working?
Against a fixed prompt set, and fixed is the whole point. We call it the Fixed Set Method: the real questions your buyers ask, gathered from sales calls, support tickets, community threads and keyword data, then held constant so every measurement afterwards is comparable to the last. We report AI share of voice per engine, mention share, answer accuracy and AI referral traffic, several runs each because engines are non-deterministic. If the questions change, the number cannot be compared.
AI says something wrong about us. Can you fix it?
Usually, and not by patching the answer. Nobody can edit a model. We find the pages the engine cited when it got you wrong and rebuild the signal there. A wrong answer is rarely a typo. It is what an engine concludes when the stale version of a fact is easier to retrieve than the current one. Fix that condition and the whole cluster of related errors goes with it.
Why does this matter more in crypto and fintech?
Because the fields engines get wrong most often are the ones that carry legal weight here: incident history, token supply, governance, fee schedules, delisted assets and invented licensing claims. Misstate a hotel check-in time and somebody is annoyed. Misstate a custody model or a regulatory status to every prospect who asks, and you have a compliance exposure nobody on your team can see, in a channel with no impressions report and no complaints inbox.
Will getting into more sources get us cited more?
It is associated with being in the conversation at all, which is the strongest relationship we have managed to measure. In our own study of 45 crypto and fintech brands, third-party presence predicted whether a brand appeared in AI answers, but not the rate at which engines cite the brand’s own site once brand size was held constant. We sell the first claim and refuse the second, because that is where the data landed.
Do you write the content?
No. We deliver strategy, architecture, templates and detailed briefs; your team or your writers execute them. In crypto and fintech that keeps your voice and your compliance review inside your business, where it legally belongs, and it keeps us on the part that needs a specialist.
What does it cost?
Retainers start at $7,500 a month, month to month after the first 90 days, scoped to a set number of tracked prompts, content briefs and outreach targets. Search and AI answers run as one program, because what moves whether an engine names you is the same authority and content work that moves search. Every tier is published on our pricing page. If you only want to watch what the engines say rather than change it, Answer Monitor is $1,500 a month. And if you are not ready for a retainer, start with the $7,500 one-time Diagnostic: your real buyer questions run through every engine, with a 90 day roadmap at the end.
Make the answer name you
See how every engine answers your buyers’ questions today, where the wrong answers come from, and what to fix first. The report lands in three weeks, then we ship the corrections and measure again at week six.