Most AI Visibility Numbers Move Because Someone Changed the Questions. The Fixed Set Method Doesn't.
· Published August 9, 2026 · Updated August 19, 2026 · 5 min read
The short version
- The Fixed Set Method is how we measure whether AI answer engines name your brand, in a way you can trust and repeat.
- Most tools quietly change the questions between runs, so their numbers move for no real reason. We do the opposite.
- Four rules: ask the same questions every time, ask each one five times, trace every wrong answer to the page that caused it, and score whether the page is even built for AI to read.
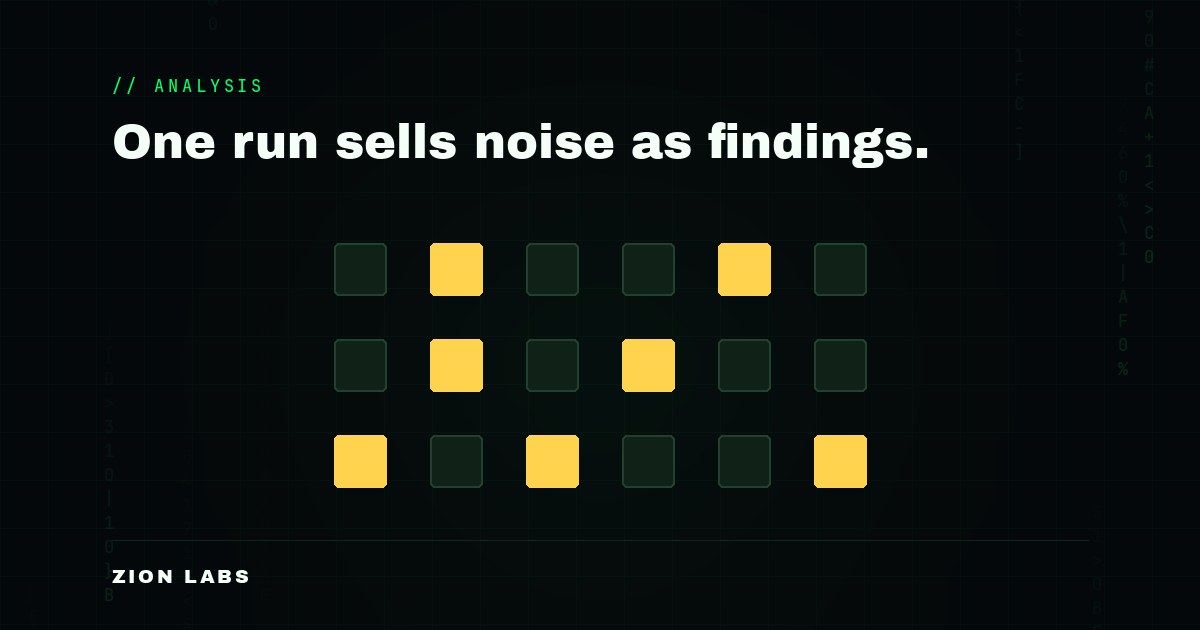
- Why it holds up: in one client scan we found 18 contradictions, and 7 showed up in just one of three runs. A single run would have sold those 7 as real, a 39% noise rate. That scan set the five run floor we use now.
- The payoff: numbers that mean the same thing next quarter, and every problem tied to a page you can fix.
What generative engine optimization means, and how we measure it
Generative engine optimization (GEO) is the work of getting AI answer engines to name, quote, and recommend your brand when they answer your market’s questions. SEO earns you a spot in a list of links. GEO earns you a spot inside the answer itself: the paragraph ChatGPT writes, the sources Perplexity lists. It is measured by how often you get cited, not by keyword rankings.
Answer engine optimization (AEO) is the close cousin: being the one direct answer to a question, like a featured snippet. We pull the terms apart in AEO vs GEO vs SEO and define GEO in full in What Is Generative Engine Optimization.
The hard part is measurement. The answer reads differently every time you ask, so how do you get a number you can trust? That is what the Fixed Set Method solves, with four rules.
Rule one: a fixed prompt set
The questions never change. Baseline your brand on fifty questions this quarter and forty different ones next quarter, and any change in the score is meaningless. You cannot tell if you improved or the test got easier.
A number that moves because someone changed the questions is a story, not a measurement. So we write the questions down at the start and reuse them exactly every time. A new question starts its own count from zero rather than quietly padding the old one.
Rule two: ask each question five times
AI engines are non-deterministic. Ask the same question several times and the answers rarely match. So one run is a single lucky or unlucky pull, not a measurement.
We saw why this matters. In one client scan across ChatGPT, Perplexity, and Gemini, running every question three times, we found 18 contradictions with the client’s own facts. 7 of those 18 showed up in only one of the three runs. A one-shot tool would have sold all 7 as real findings, shipping noise at a 39% rate. That scan ran three times per question and it is the reason we now run five, which is the floor every number we publish is measured at. Several runs tell you what an engine actually tends to say.
Rule three: trace every error to a page
Finding that an engine is wrong about you is half a result. The half that matters is knowing why.
Nobody can edit a model. We control every input it reads. You cannot call OpenAI and fix their weights, but you can find the page the engine pulled from and fix that. So we trace each wrong answer back to its source, using the links and citations the engines attach themselves. In that scan, one contradiction traced straight to a page on the client’s own site, one they could edit that afternoon. When a wrong answer cannot be traced, we say so, rather than blaming whichever source happened to be listed first.
Rule four: score the page for AI
An engine can only cite a page it can reach and read cleanly. Many pages fail before citation is ever in play: they block AI crawlers, bury the answer, or break into chunks that make no sense alone.
The Retrieval Readiness Score is our free nine-check scan of a single page for exactly those problems. It will not create demand for you on its own, and we have published our finding that readiness does not predict your citation rate once brand size is accounted for. What it does is clear the reasons an engine cannot use your page in the first place.
How the four rules fit together
Fix the questions so the ruler does not move. Ask each one several times so a fluke is not a finding. Trace every error to a page you can fix. Score the page so AI can read it at all. Then run the same set again and watch the number move for a real reason.
Each rule closes one way of fooling yourself. Change the questions and you fake progress. Ask once and you ship noise. Skip the trace and you have a complaint, not a fix. Skip the readiness check and you polish a page AI cannot read.
Where to start
Want this run on your own brand? Our AI Visibility Audit applies the full method: a fixed question set for your market, several runs across the major engines, every wrong answer traced to a page, and a readiness pass on the pages that matter.
Or start yourself. The free tools need no login. Run the Retrieval Readiness Score on your most important page first, to see if it is even in the game.
Revision history
- Sampling floor stated as five runs per question, matching the harness default and the three other pages that already publish five. The 39% noise anecdote is unchanged and still described as the three run scan it came from, now framed as the evidence that set the five run floor. No measured figure was altered.
- Retitled so the page leads with the problem rather than the method name, keeping 'The Fixed Set Method' in the title because the phrase is used as link text elsewhere on the site. The description no longer repeats the opening sentence of the title. No figure or body claim changed.
- Published.